Open source & on PyPI
vit-xray is MIT licensed, built on timm, and one pip install away. Grab it, point it at a photo, and see what your backbone is really doing.
Here's something that surprised me the first time I saw it. Take a pretrained vision transformer, the kind of backbone half of us freeze and build on top of, feed it a photo, and look at the patch tokens coming out the other end. You'd expect every token to describe its own little patch of the image. Mostly, they do. But scattered across the image, usually in the most boring places, like empty sky, a blank wall, flat ground, you'll find a few tokens glowing roughly ten times brighter than everything around them. They aren't describing their patch anymore. The model has quietly hijacked them.
I built vit-xray so you can see this for yourself, on your own images and your own backbone, with one command:
pip install vit-xray
vit-xray photo.jpg
No GPU? No problem. The default backbone is a 329 MB CLIP model, and the whole thing runs in about ten seconds on a laptop CPU, peaking around 1.5 GB of RAM.
If you'd rather hear me walk through it, I put together a five-minute narrated explainer:
So What's Actually Going On?
A vision transformer cuts an image into patches and gives each patch a token. Now imagine you're the model, and you're looking at a patch of clear blue sky that looks exactly like the patch next to it, and the one next to that. There's nothing new to store there. So a large, well-trained model learns to recycle that token as scratch space, a place to stash global information about the whole image.
Clever, but it comes at a price. Those tokens end up with an L2 norm about ten times larger than their neighbours, and whatever sits under them is no longer described by them. This phenomenon was named and measured by Darcet et al. in Vision Transformers Need Registers (ICLR 2024): roughly 2% of tokens, only in large enough models trained long enough.
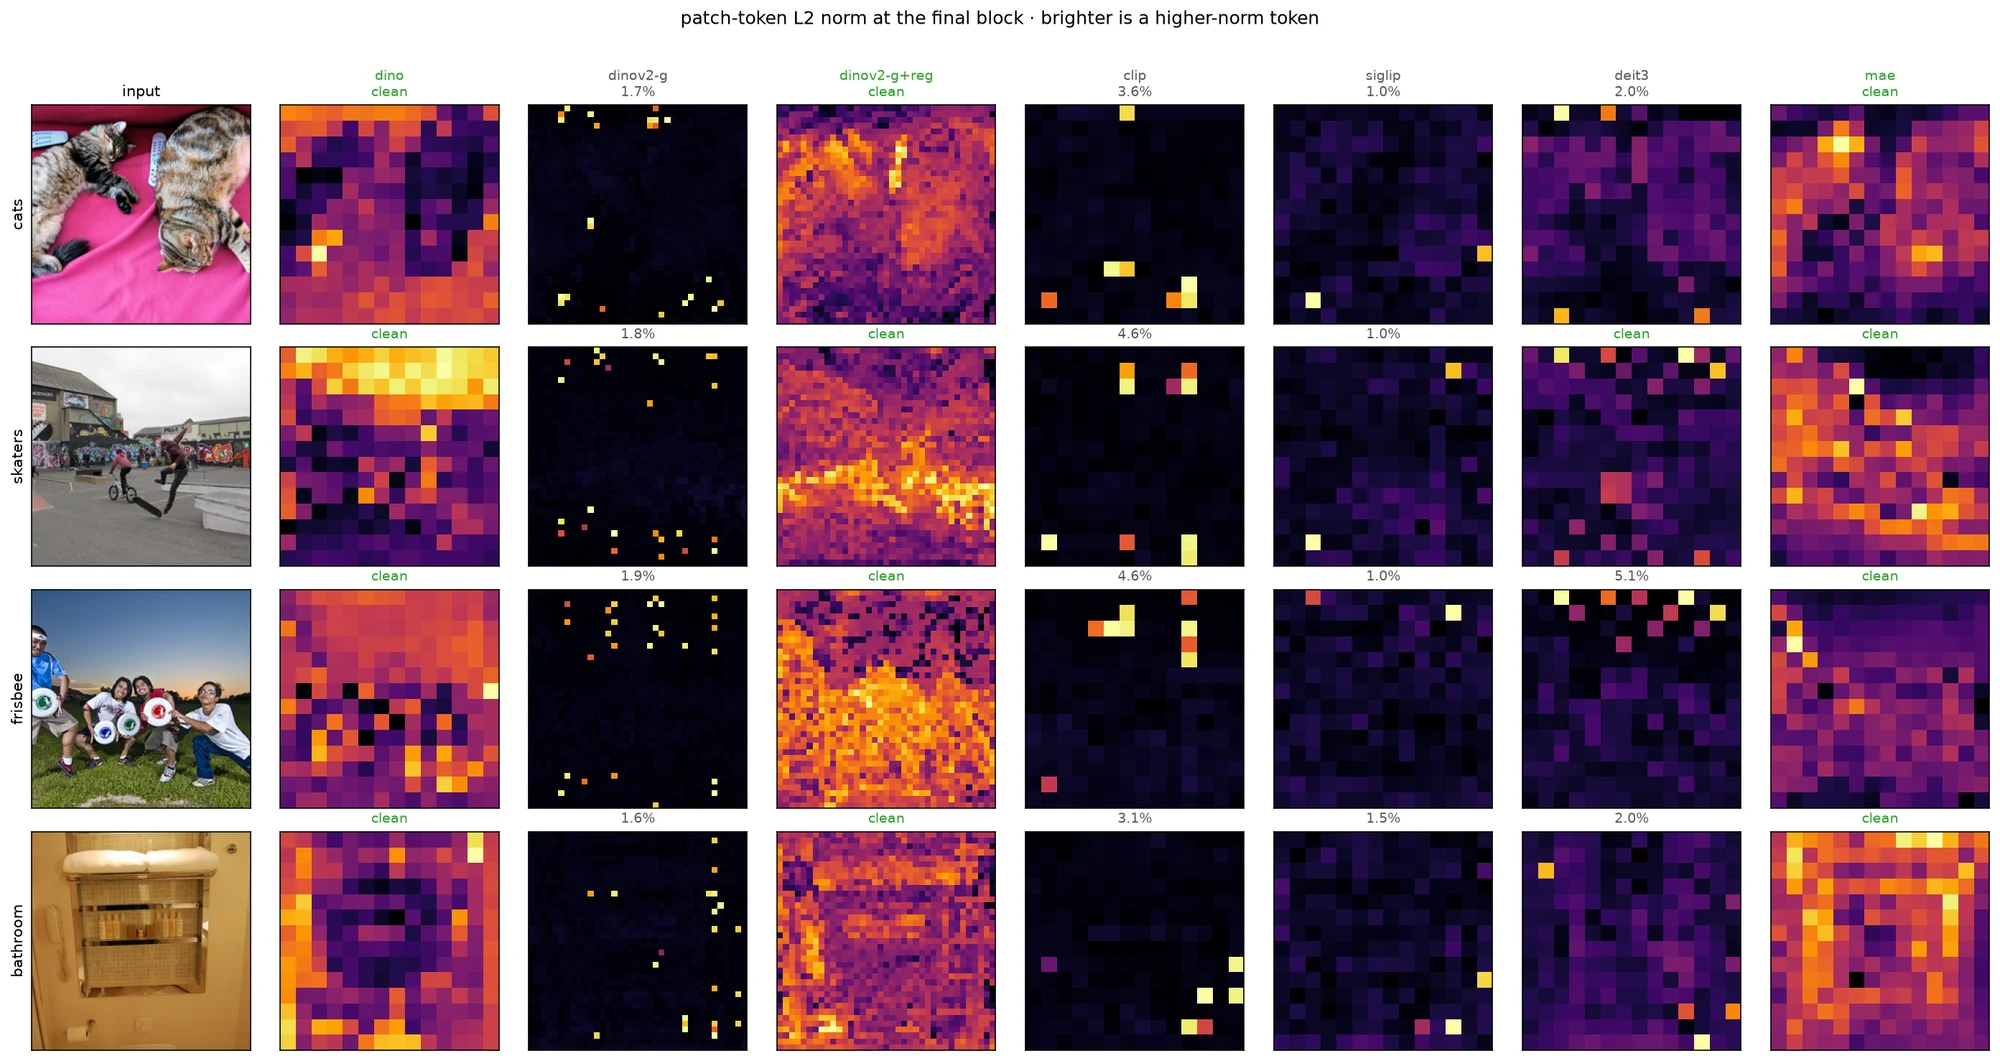
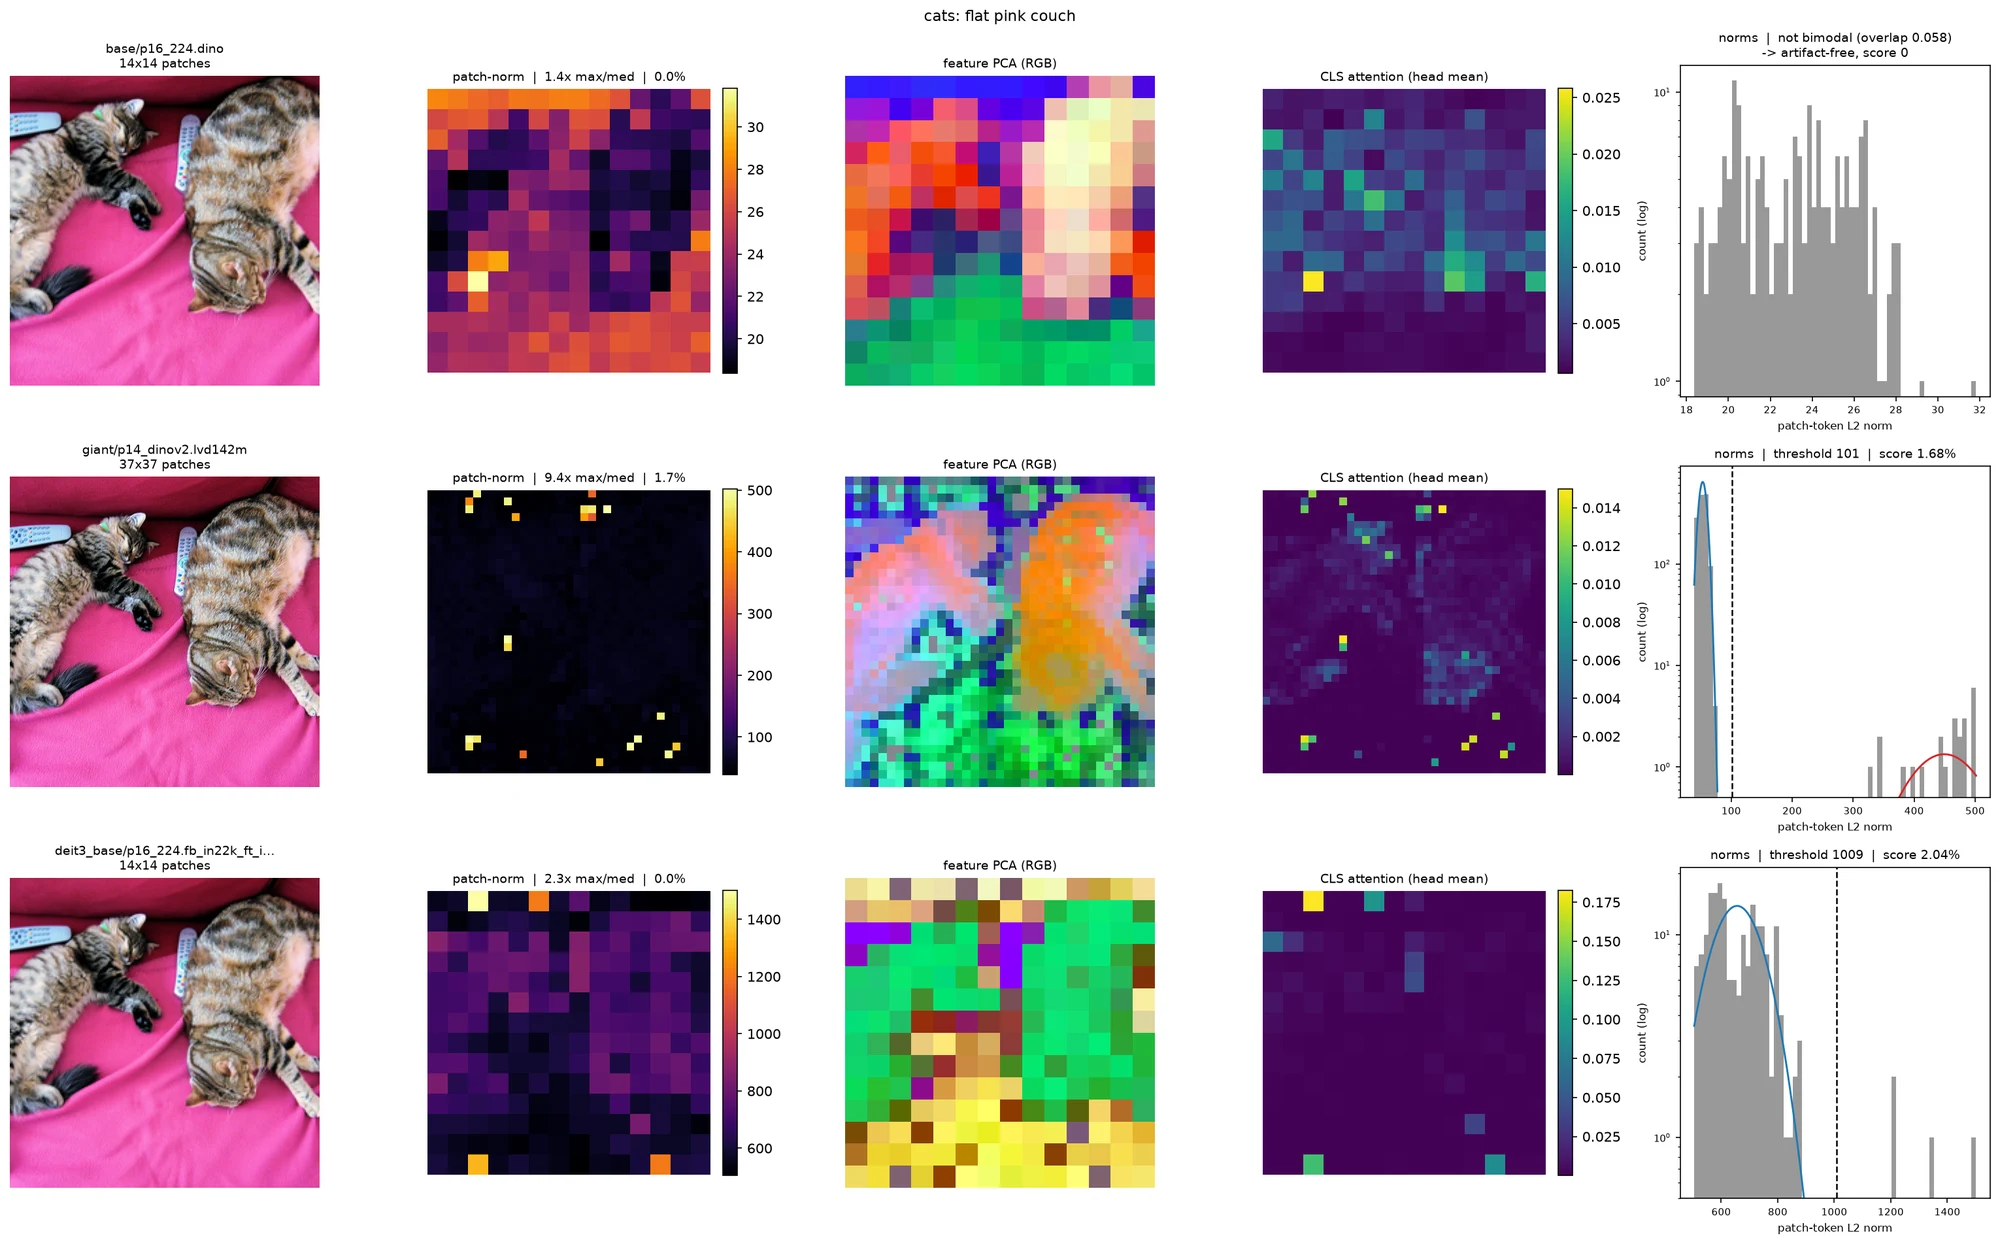
Here's the full picture: patch-token norms at the final block for seven pretrained backbones and four images. The bright dots are the hijacked tokens, and notice where they land: sky, walls, flat ground. DINO, MAE, and DINOv2 with registers stay clean.
What vit-xray Shows You
For every image and every backbone, you get three views plus a single number:
- 📊 Patch-norm map: the L2 norm of every patch token. Artifacts pop out as isolated bright dots.
- 🎨 Feature PCA: the patch tokens projected down to three components and shown as RGB. It's the pseudo-segmentation view, and it shows you how the backbone groups the scene.
- 👁 CLS attention: what the class token is looking at. When artifacts are present, the attention spikes on them instead of the objects.
- 🩻 Artifact score: the fraction of tokens that belong to the high-norm population.
I want to be upfront about how that score works, because it's the part I cared most about getting right. There is no hardcoded cutoff. The paper's own threshold was hand-picked for one model, and it says outright that the right value varies. So instead, vit-xray fits a two-component Gaussian mixture to the token norms and puts the threshold where the two components cross. If the norms aren't meaningfully bimodal, the score is zero and the backbone is reported clean. No magic numbers to tune per model.
The Fix: Registers
Here's the part I love. The fix proposed by Darcet et al. is almost embarrassingly simple: give the model a few dedicated extra tokens, registers, to use as scratch space, so it stops stealing patch tokens for the job.
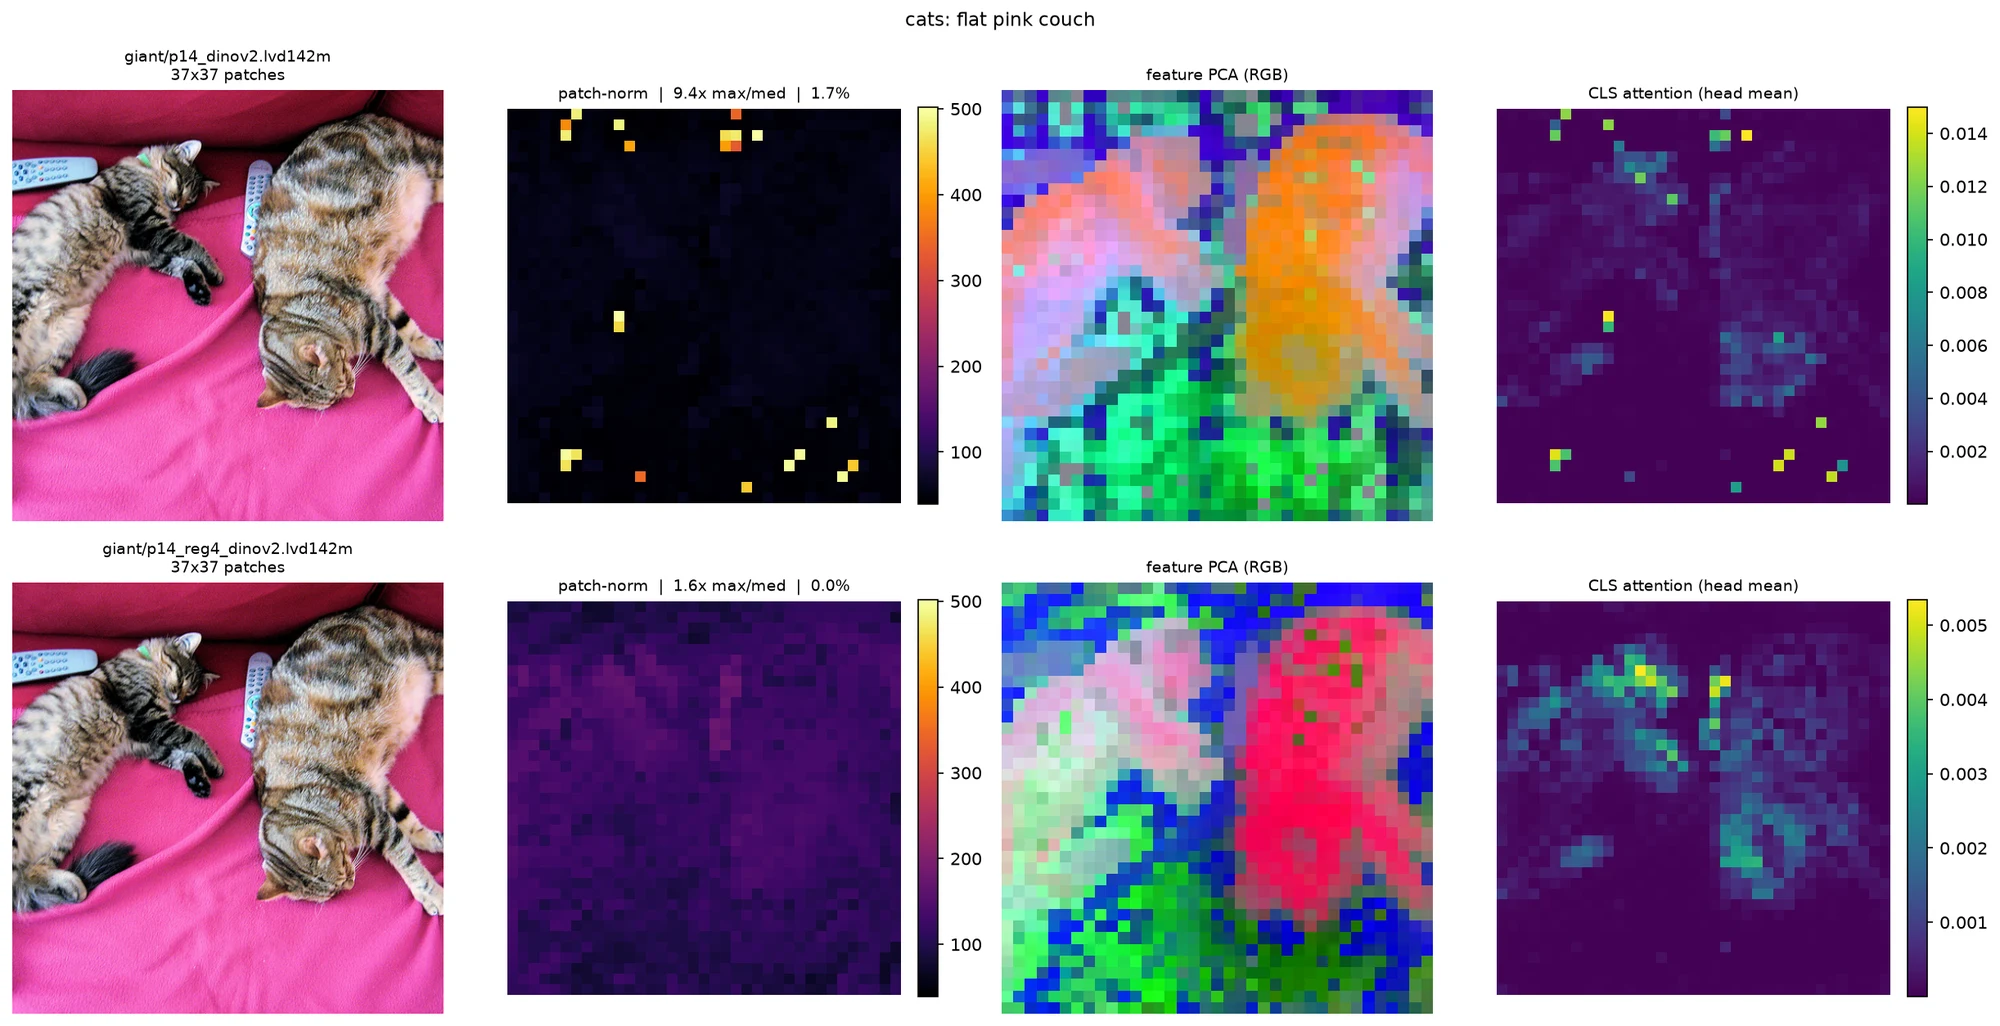
Below is the same architecture, same width, same training data, on one shared colour scale. Registers are the only difference. Keep your eye on the attention panel on the right: without registers it spikes on the artifacts; with them, it traces the cats.
You can also see the problem in the raw numbers. A backbone with artifacts has a visibly bimodal norm distribution: a big bulk, a gap, and a small cluster of high-norm tokens. That gap is exactly where vit-xray's fitted threshold lands. DINO has no gap at all.
Why You Should Care
If you're freezing a backbone and reading its patch tokens for semantic segmentation, monocular depth, feature fields, open-vocabulary detection, or robotic semantic mapping, then those artifact tokens are corrupted inputs to your dense head. They carry global information, not local, so whatever is sitting underneath them gets described wrongly.
This isn't just cosmetic. Darcet et al. showed it measurably hurts dense prediction and breaks unsupervised object discovery: DINOv2 was actually worse than supervised baselines with LOST until registers were added.
My pitch is simple: it costs one command to find out which kind of backbone you have. If yours comes back clean, great, forget about all of this. If it doesn't, pick a register-trained variant, or look at the training-free fix in Vision Transformers Don't Need Trained Registers.
Works With Any timm ViT
vit-xray isn't tied to a handful of models. Any timm vision transformer works. The patch grid and the number of prefix tokens are read from the model itself, never hardcoded, so a plain ViT (one CLS token) and DINOv2 with registers (five prefix tokens) both come out right. Here's what I measured on the seven backbones in the gallery:
| model | cats | skaters | frisbee | bathroom |
|---|---|---|---|---|
| vit_base_patch16_224.dino | 🟢 clean | 🟢 clean | 🟢 clean | 🟢 clean |
| vit_giant_patch14_dinov2.lvd142m | 🟡 1.7% | 🟡 1.8% | 🟡 1.9% | 🟡 1.6% |
| vit_giant_patch14_reg4_dinov2.lvd142m | 🟢 clean | 🟢 clean | 🟢 clean | 🟢 clean |
| vit_base_patch16_clip_224.laion2b | 🟡 3.6% | 🟡 4.6% | 🟡 4.6% | 🟡 3.1% |
| vit_base_patch16_siglip_224.webli | 🟡 1.0% | 🟡 1.0% | 🟡 1.0% | 🟡 1.5% |
| deit3_base_patch16_224.fb_in22k_ft_in1k | 🟡 2.0% | 🟢 clean | 🟡 5.1% | 🟡 2.0% |
| vit_base_patch16_224.mae | 🟢 clean | 🟢 clean | 🟢 clean | 🟢 clean |
Two honest caveats about that table, because I'd rather you hear them from me:
- SigLIP has no CLS token. It pools instead, so there's nothing to compute CLS attention from. The other panels still render, and the attention panel tells you so rather than crashing.
- DeiT3 reads clean on one image and 5.1% on another. Its artifacts are real and stable: the same four border tokens sit at a norm of about 1500 from block 3 onward. But its ordinary tokens inflate over the last few blocks until they nearly catch up, so how separable they look at the final block depends on the image. Reading a mid-network block with
--layer 6shows it unambiguously.
That second point generalizes, and it's worth remembering: artifacts can appear mid-network and be erased by the last block, so a clean final-block reading isn't always the same as no artifacts.
Using It
For the clearest picture, use the model my figures lead with, DINOv2 ViT-g/14. It gives you a 37×37 patch grid instead of 14×14 and roughly twenty outlier tokens instead of seven. Fair warning, it's a 4.3 GB download and needs about 10 GB of RAM on CPU, which is exactly why it isn't the default.
vit-xray photo.jpg --model vit_giant_patch14_dinov2.lvd142m --all-panelsA few flags I reach for all the time:
vit-xray photo.jpg -m modelA -m modelB   # compare backbones, one row each
vit-xray photo.jpg --layer 6              # read a mid-network block
vit-xray photo.jpg --pca-foreground       # mask the PCA background
And if you'd rather stay in Python, it's a library too:
from vit_xray import inspect

res = inspect("photo.jpg", model="vit_base_patch16_clip_224.laion2b")

res.norm_map        # (H, W)
res.pca_rgb         # (H, W, 3)
res.attention       # (H, W), or None if the model has no CLS token
res.artifact_score  # float
res.plot()          # matplotlib Figure
Every figure on this page is reproducible from the repo with a single vit-xray --gallery configs/gallery.yaml. It pulls four COCO images picked for their large, low-information regions, runs the whole model zoo, and the output is deterministic, the same figures pixel for pixel on every run.
What It Isn't
vit-xray answers exactly one question: are this backbone's patch features clean? I deliberately didn't reimplement other kinds of looking-inside. If you want attention rollout across all layers, use vit-explain. If you want to know why the model made this prediction, reach for pytorch-grad-cam. They're complementary, and they do their jobs well.
Give it a try on your own backbone, and if you find something interesting, I'd love to hear about it.